Do we still have to denormalize? Have your schema and search it too
Source Entity
Hacker News
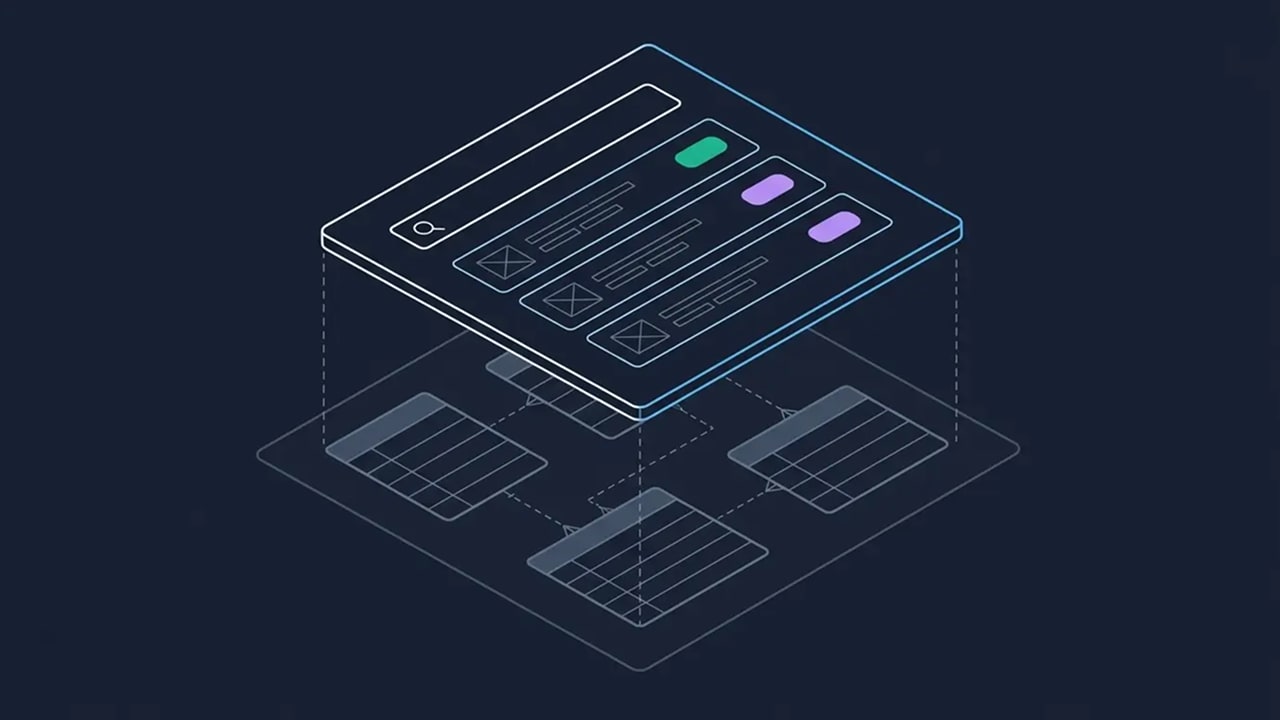
Stu Hood discusses the technical tension between database normalization and search performance. The article highlights how ParadeDB aims to bridge this gap by optimizing search joins within relational structures.
The Dilemma of Database Architecture
For decades, database architects have faced a fundamental trade-off: the clean, logical structure of normalized relational schemas versus the high-performance requirements of modern search functionality. As Stu Hood highlights in his October 2026 analysis, the industry has historically forced engineers into a binary choice. One path involves maintaining a normalized relational database (like PostgreSQL) while accepting the performance penalties of complex joins. The alternative is the creation of a 'fragile' ETL (Extract, Transform, Load) pipeline that syncs data into a secondary search engine like Elasticsearch, which requires denormalizing the data to achieve speed.
The Cost of Denormalization
Denormalization, while effective for read-heavy search operations, introduces significant technical debt. By flattening relational structures—such as combining users, posts, and comments into a single table—developers sacrifice data integrity and consistency. This approach necessitates constant synchronization between the primary database and the search index. As Hood points out, this creates brittle systems where schema changes in the relational source can break the downstream search index, leading to data drift and complex maintenance requirements.
Challenges of Search Joins
Searching across multiple joined tables, often referred to as a 'search join,' remains a notorious bottleneck in database management. When a user requests results sorted by relevance—using metrics like BM25 or vector similarity—the database must compute these values across vast datasets. In a normalized environment, this requires joining millions of rows before the scoring algorithm can even begin its work. Traditional relational databases were not originally optimized for this type of high-concurrency, relevance-based retrieval, leading to the performance latency that engineers have struggled to mitigate.
The Promise of ParadeDB
The emergence of tools like ParadeDB signals a shift in how we approach search within relational databases. By attempting to make search joins performant directly within the database engine, ParadeDB seeks to eliminate the need for external search indexes. This architecture allows developers to keep their data in its native, normalized form while still achieving the speed necessary for modern application requirements, such as faceting and ranking results.
Future Trends in Data Retrieval
As the volume of data grows, the pressure to abandon inefficient ETL processes will only increase. Future trends suggest a move toward 'unified' databases that treat search as a first-class citizen rather than an auxiliary service. If technologies can successfully optimize search joins, we may see a decline in the reliance on secondary search clusters, simplifying the overall tech stack for developers and reducing the operational overhead associated with maintaining disparate data silos.
Conclusion
Ultimately, the ability to 'have your schema and search it too' represents the holy grail of database design. By addressing the historical limitations of Postgres and similar systems, the industry is moving closer to a future where developers no longer have to sacrifice structural integrity for search speed. While the challenge of optimizing joins remains significant, the evolution of database technology suggests that the era of fragile, denormalized ETL processes may finally be nearing its end.