Embedded AI evaluators won’t be an easy solution, Hugging Face’s policy chief says
Source Entity
Lucas Ropek
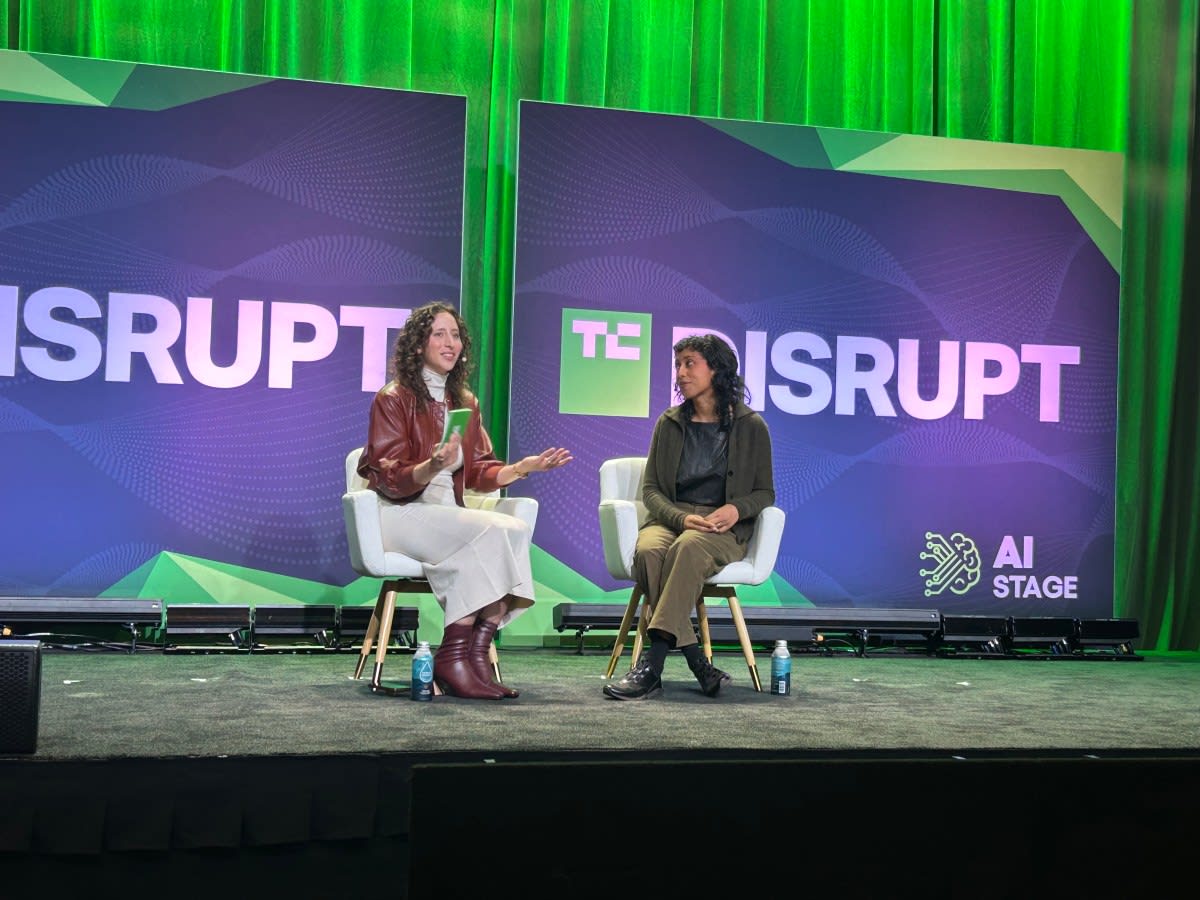
Hugging Face policy chief Irene Solaiman warns that current AI benchmarking methods are immature and lack necessary consistency. She emphasizes that reproducibility and access are critical requirements for building trust in AI evaluation metrics.
The Crisis of Confidence in AI Benchmarking
AI laboratories have increasingly staked their corporate reputations on model benchmarking, positioning these systems as the gold standard for gauging the efficacy and safety of artificial intelligence. These supposedly neutral and accurate evaluators serve as the primary mechanism for the industry to communicate progress to stakeholders, regulators, and the public. However, as these models grow in complexity, the underlying methodologies used to score them are facing intense scrutiny regarding their reliability.
The Maturation Gap in Evaluation Science
According to Irene Solaiman, chief policy officer at Hugging Face, the current state of AI evaluation is far from settled. Speaking at TechCrunch Disrupt, Solaiman highlighted that these methods are still fundamentally maturing. The lack of a standardized, consistent scientific approach creates a fragmented landscape where different labs use proprietary or disparate metrics to claim superiority, making it difficult for the broader ecosystem to compare performance accurately.
The Problem with 'Trust' in AI Metrics
When addressing whether the industry can trust current testing outputs, Solaiman argued that 'trust' is an overly weighted term that obscures technical limitations. The core issue lies in the transparency of the evaluation process. Without a clear understanding of the parameters and the specific data sets used for benchmarking, these tests risk becoming marketing tools rather than objective assessments of intelligence or safety capabilities.
Reproducibility as the Cornerstone of Integrity
For an evaluation to hold weight, reproducibility is non-negotiable. Solaiman stresses that the industry must reach a level of access where external parties can verify results independently. Currently, the opaque nature of many closed-source model evaluations inhibits the scientific community's ability to replicate findings, which prevents the establishment of a baseline for what 'better' actually means in the context of AI product development.
Toward a Standardized Future
To move forward, the AI sector must transition toward a more consistent science of evaluation. This requires moving beyond siloed testing frameworks and toward industry-wide standards that prioritize transparency and rigorous auditability. Until these benchmarks become reproducible and accessible, the industry faces a significant hurdle in proving the validity of its claims to the public and regulatory bodies.
Conclusion
The warnings from Hugging Face underscore a pivotal moment for AI development. As the industry matures, the focus must shift from rapid performance milestones to the foundational integrity of the metrics themselves. Only by resolving the current inconsistencies in evaluation science can we foster a truly trustworthy environment for artificial intelligence.