Underdog shows off a 32MB speech model in new demo
Source Entity
Ivan Mehta
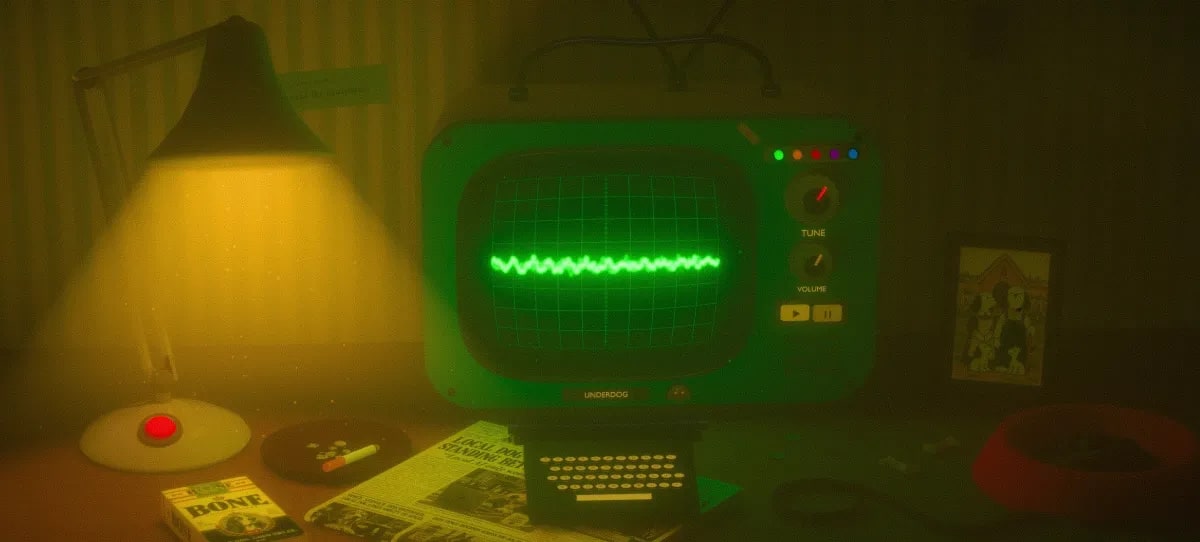
Underdog has released 'Woof,' a highly efficient 32MB text-to-speech model capable of generating both speech and music. This innovation highlights a growing industry shift toward lightweight, edge-based AI that operates without reliance on massive cloud infrastructure.
The Rise of Edge AI: Underdog’s 32MB Breakthrough
In an industry currently obsessed with the 'bigger is better' philosophy, the startup Underdog has introduced a disruptive approach to artificial intelligence with its new model, 'Woof.' While major tech giants continue to pour billions into gargantuan Large Language Models (LLMs) that require massive server farms and significant electricity, Underdog has unveiled a text-to-speech and music generation model that clocks in at a mere 31.7 MB. This development represents a significant pivot toward 'edge AI,' where intelligence is processed locally on consumer hardware rather than in the cloud.
Challenging the Cloud-Centric Paradigm
The prevailing trend in AI development has been the reliance on centralized cloud providers, which handle heavy computational tasks and return results to the user. This model poses significant issues regarding latency, privacy, and infrastructure costs. By creating a model that fits into such a small footprint, Underdog is directly challenging the necessity of these 'intrusive' cloud providers. The thematic design of their demo game—featuring a retro tech aesthetic with a typewriter and CRT monitor—serves as both a nostalgic nod and a pointed critique of the modern, cloud-dependent AI ecosystem.
Functionality Within Constraints
It is technically remarkable that a 32MB package can handle both speech and music synthesis. Typically, high-fidelity audio generation requires substantial parameter counts and deep learning architectures that are far too bulky for a standard mobile device. Underdog’s ability to compress these capabilities into a sub-32MB file suggests advancements in model quantization or architecture efficiency that could redefine how developers integrate voice features into local applications.
The Future of Localized Intelligence
The implications for this technology are vast. By enabling voice and music generation on local devices like smartphones and laptops, companies can ensure greater user privacy and provide seamless, offline functionality. This democratization of AI capabilities—moving them from massive, expensive data centers to the hardware already in our pockets—is likely to become a major trend as developers seek to lower latency and reduce the carbon footprint associated with large-scale model inference.
A New Frontier for Lightweight Models
As we look forward, the success of Underdog’s 'Woof' model may force a reassessment of how we measure AI progress. Instead of just tracking parameter counts or benchmarks that require supercomputers, the industry may begin to prioritize performance-per-megabyte. If Underdog can maintain this level of quality while keeping the file size minimal, they have established a blueprint for a more sustainable, private, and accessible future for generative AI technology.