Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline
Source Entity
Hugging Face - Blog
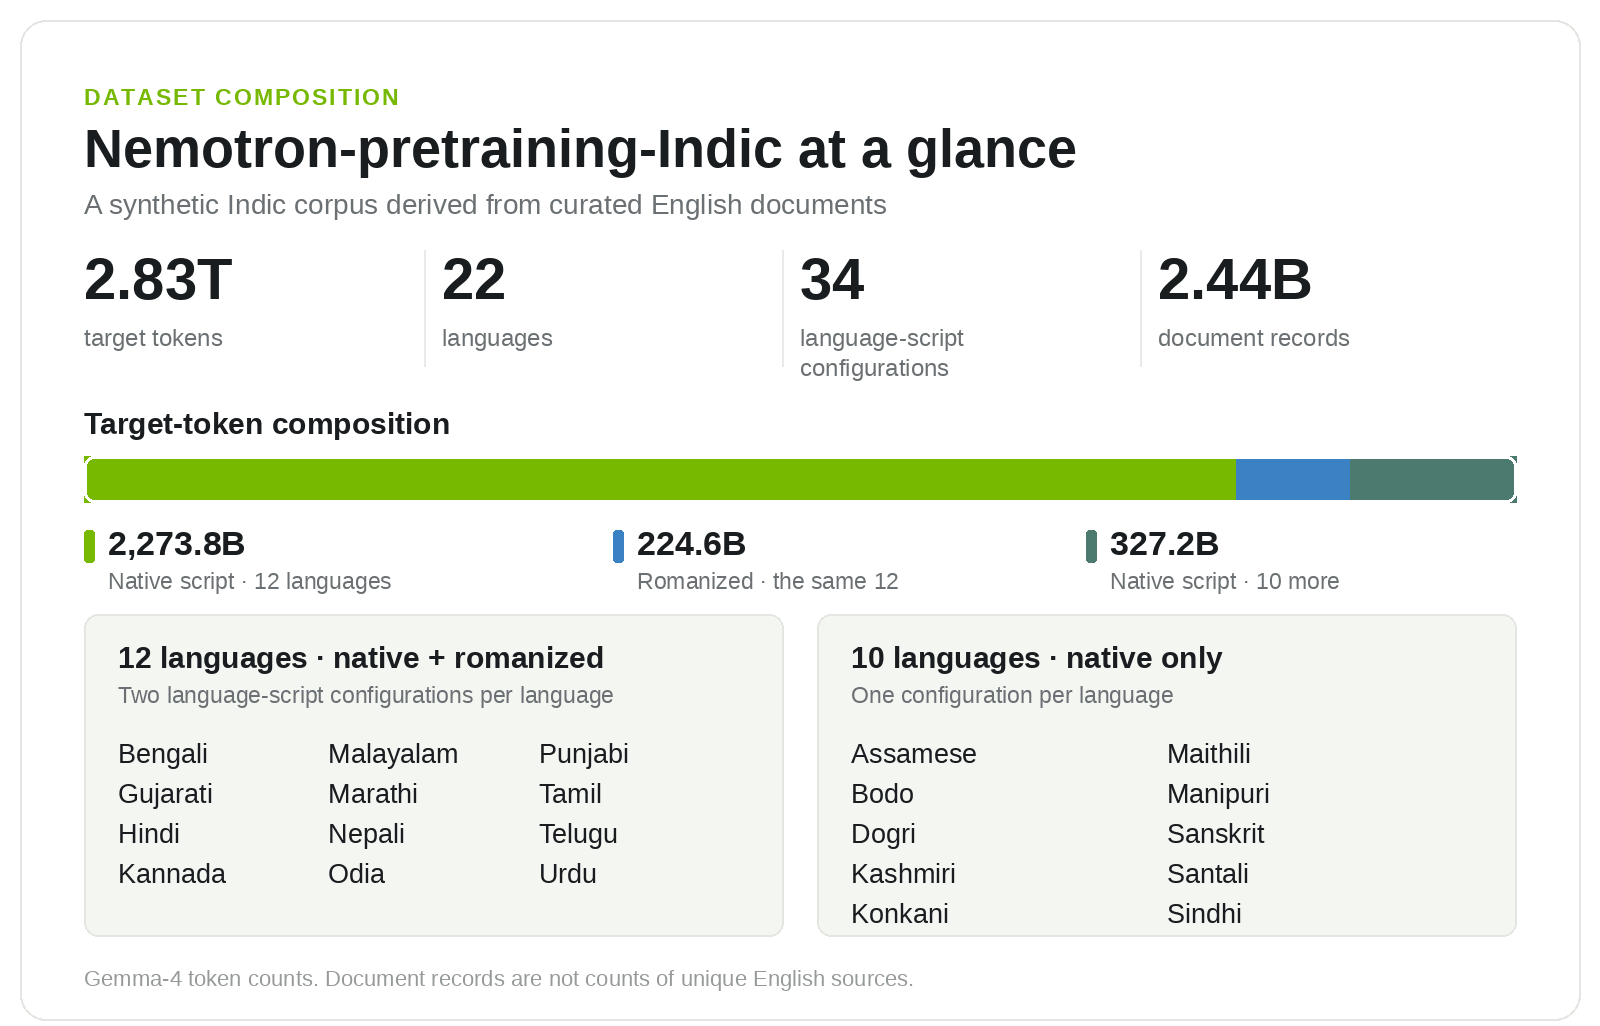
AI4Bharat and NVIDIA have partnered to release Nemotron-pretraining-Indic-v1, a massive dataset of 2.8 trillion tokens covering 22 Indian languages. This initiative includes an open-source, GPU-accelerated pipeline designed to enhance AI performance for nearly 1.2 billion native speakers.
Bridging the Digital Divide: The Nemotron-Indic Initiative
The recent announcement by AI4Bharat and NVIDIA regarding the release of 'Nemotron-pretraining-Indic-v1' marks a significant milestone in the landscape of Large Language Model (LLM) development. By curating a massive corpus of 2.8 trillion tokens spanning the 22 languages officially recognized by the Indian Constitution, the project addresses a long-standing technological disparity: the scarcity of high-quality training data for non-English, Indic languages. This initiative is not merely a technical release; it is a fundamental shift toward democratizing access to advanced AI for the nearly 1.2 billion citizens who utilize these languages as their primary means of communication.
The Scale and Technical Architecture
The sheer scale of 2.8 trillion tokens is designed to provide the linguistic depth required to train modern, high-performance generative models. Beyond raw volume, the authors—led by researchers from AI4Bharat and NVIDIA—have emphasized the inclusion of native-script data for 22 languages and romanized data for twelve. This dual approach is critical, as it accounts for the diverse ways users interact with digital platforms in India, where code-switching and romanized script usage are prevalent in daily digital discourse.
Innovation in Data Engineering
One of the most consequential aspects of this announcement is the open-source, GPU-accelerated pipeline developed to facilitate this project. Traditionally, the process of cleaning, translating, and assessing data quality for low-resource languages has been a manual and prohibitively expensive bottleneck. By providing a reusable pipeline that handles translation, quality assessment, and repair, the team has effectively lowered the barrier to entry for future researchers and developers looking to contribute to the Indic language AI ecosystem.
Collaborative Synergy: IIT Madras and NVIDIA
The collaboration between NVIDIA and IIT Madras leverages the technical expertise of a premier global hardware leader alongside the deep linguistic and regional knowledge of India's foremost engineering institute. This partnership underscores the importance of academic-industry cooperation in solving complex, large-scale problems. By utilizing GPU-accelerated workflows, the team has demonstrated that the computational intensity required for such massive data processing can be managed efficiently, setting a new standard for future pretraining efforts.
Societal and Future Implications
The implications of this development are profound for the future of digital inclusion in India. By anchoring the dataset in the languages spoken by 97% of the population, the project creates a foundation for local-language AI applications, from automated government service delivery to personalized healthcare and education tools. As these models move from pretraining to deployment, they will likely catalyze a new wave of innovation, enabling technology to transcend the English-language barrier that has historically marginalized large segments of the Indian population.
Conclusion
In summary, the release of Nemotron-pretraining-Indic-v1 represents a sophisticated fusion of linguistic representation and high-performance computing. By addressing the data scarcity issue through a transparent and scalable pipeline, AI4Bharat and NVIDIA are not only advancing the state of AI research but are also providing the essential infrastructure for an inclusive digital future in India.